Tag: technology

  • Migration as a catalyst for test architecture redesign

    When our team decided to move our Playwright tests from C# to TypeScript, I thought the job was clear. We would rewrite the tests in a new language, check that they still pass, and move on.

    It didn’t work out that way. Almost every test I opened had something behind it that didn’t survive the move: data that only existed on one environment, a login at the start of every test, a setup step somebody used to do by hand before a run. If we had translated those tests line by line, we would have ended up with the same problems, just in TypeScript.

    So we treated the migration as a chance to rebuild how the framework works.

    In this post I want to share what we changed and what I would do the same way again. Some of it is specific to Playwright, but most of it applies to any test framework migration.

    A bit of context first: the product is an enterprise web application with several user roles, and we had around 200 Playwright UI and API tests in C#, running in Azure Pipelines.

    Why TypeScript

    Playwright written with .NET does its job, but TypeScript is Playwright’s home language. The test runner, fixtures and tracing are designed for it first, new features usually arrive there before other languages, and there’s far more community material when you get stuck. We also expected to write less framework code of our own. And AI coding assistants handle Playwright in TypeScript much better than in C#, which mattered for how we planned to do the migration (more on that later).

    Deciding which tests to migrate

    We didn’t move every test across as it was. Going through the old suite one test at a time, we kept asking whether each check really needed a browser. Quite often it didn’t. Many checks, like whether a role is allowed to do something, can be tested faster and more reliably through the API, and some logic is better covered by unit tests closer to the code.

    We rebalanced coverage across unit, API and UI levels. In the end we cut the number of end-to-end tests by 40%, while keeping every critical user path covered in the UI.

    The framework underneath changed even more than the tests: how tests get their data, how they log in, where setup lives and how the project is organised. That’s where most of our old problems were, and the rest of this post is about those changes.

    Test data the tests can rely on

    The first thing that broke during the migration was test data.

    Our old tests used whatever happened to be on the environment. IDs and user names were hardcoded in the test code, so a suite that passed on one environment could fail on another simply because the records it expected weren’t there.

    We fixed this by giving every test suite its own precondition data. It describes everything the suite needs before the first test runs: the initial user data, folder structure and the test files themselves. On top of that, every environment has its own JSON with the data that already exists there, such as IDs and names, so the nightly run can use it straight away. Our rule was to create only what a suite needs, and only when it needs it.
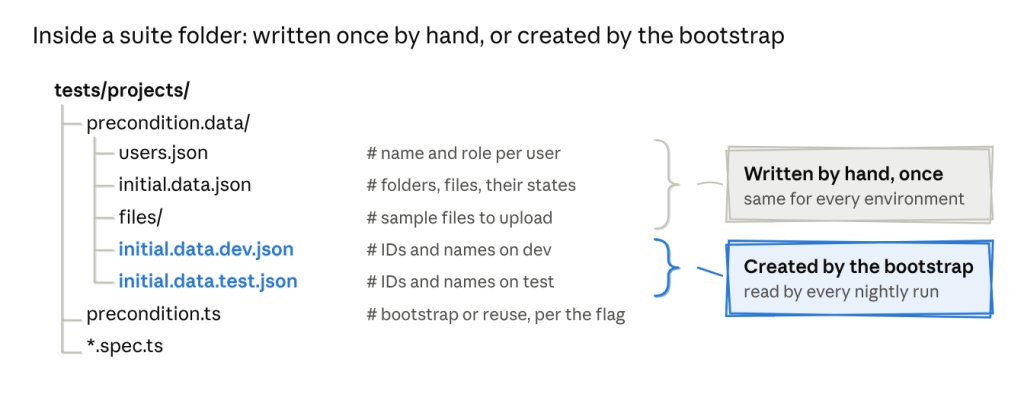
    Now, if I want to know what a suite depends on, I open its folder. Nothing is hidden in a shared environment or in someone’s head.

    We also separated two kinds of data.

    Values that never change, like roles, statuses and permission levels, live in enums and constants. Everything a test creates, such as project names and descriptions, is generated with Faker, so each run works with fresh records.

    export enum Role {
    Admin = 'admin',
    Manager = 'manager',
    Contributor = 'contributor',
    }
    import { faker } from '@faker-js/faker';
    export interface Project {
    name: string;
    description: string;
    }
    export const newProject = (): Project => ({
    name: `Project ${faker.string.alphanumeric(8)}`,
    description: faker.lorem.sentence(),
    });

    I didn’t expect this part to matter for speed, but it did. Once tests stopped sharing records, we could run them in parallel without them getting in each other’s way.

    Generating data or reusing it

    The precondition files describe what a suite needs, but someone still has to put that data on the environment. Before the migration, that someone was usually a person. We prepared data by hand on new environments, tests passed only where the data had been set up, and when a test failed it was hard to tell what state it had run against.

    We looked at two obvious options.

    1. Generating everything before each run keeps tests clean and isolated, but it’s slow and puts a lot of load on the database.
    2. Reusing existing data, which is what the old suite did, is fast, but over time the data drifts and tests quietly start depending on each other.

    We ended up with something in between. It took more work to build, but it gave us the speed of reusing data with most of the reliability of generating it.

    One environment variable, DATA_GENERATION, decides which path a suite takes:
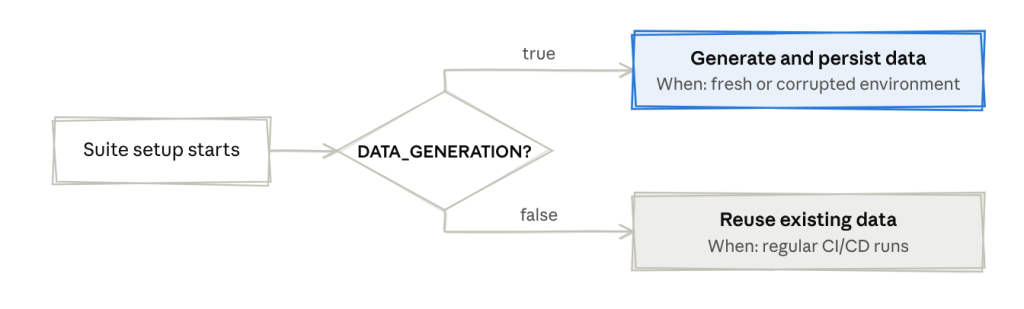
    When it’s true, the setup creates everything from the precondition files and saves what it created. We use this on a new environment, or when the data has got into a bad state. When it’s false, which is the default for CI runs, the setup skips all of that and loads the data from the last bootstrap.

    // tests/precondition.ts
    export async function prepareSuiteData(): Promise<SuiteData> {
    const shouldGenerateData = process.env.DATA_GENERATION === 'true';
    if (!shouldGenerateData) {
    return loadSuiteData();
    }
    const suiteData = await createFromPreconditions(precondition);
    await saveSuiteData(suiteData);
    return suiteData;
    }

    Nobody prepares data by hand anymore, and setting up a new environment is one pipeline run with the flag switched on.

    Logging in once per role

    In the old suite, almost every test started with a login through the UI. That made runs slow, and because login involves redirects and timeouts, it was also one of our most common sources of flaky failures. A test about permissions could fail because the login page was slow that morning. Environments with two-factor authentication couldn’t be tested at all.

    Now authentication happens once per role, in a setup step that runs before the tests.

    For each role, the setup reads the password and 2FA secret from our secret vault, logs in, and saves the browser storage state to a file in an .auth folder: admin.json, manager.json and contributor.json. It also stores the role’s API token, so tests that call the API directly can reuse it.

    // auth.setup.ts
    import { test as setup } from '@playwright/test';
    import { roles } from './config/roles';
    import { getSecrets } from './helpers/secrets';
    import { login, getApiToken, saveApiToken } from './helpers/auth';
    for (const role of roles) {
    setup(`authenticate as ${role}`, async ({ page, request }) => {
    const credentials = await getSecrets(role); // password and 2FA secret from the vault
    await login(page, credentials); // UI login, including the 2FA step
    await page.context().storageState({ path: `.auth/${role}.json` });
    await saveApiToken(role, await getApiToken(request, credentials));
    });
    }

    In a test, choosing a role is one line at the top of the describe block:

    test.describe('Manager permissions', () => {
    test.use({ storageState: '.auth/manager.json' });
    test('UI80105: Manager adds a project shared with all users - should be visible to everyone', async ({ page }) => {
    // the test starts already logged in as a manager
    });
    });

    Saved sessions come with their own risks. They expire, and a test can end up depending on something the login step left behind without anyone noticing. We handle expiry with a session refresh, so an old session gets renewed instead of failing the run.

    One thing we got almost for free: because the setup generates the 2FA code from the secret, we can finally run the suite against environments with MFA enabled.

    Running in CI from the start

    We put migrated tests into the pipeline from the first days of the migration instead of waiting until everything was moved.

    Looking back, this was one of our better decisions. Problems with data, sessions and parallel runs showed up while the design was still easy to change, not after we had built 200 tests on top of it.

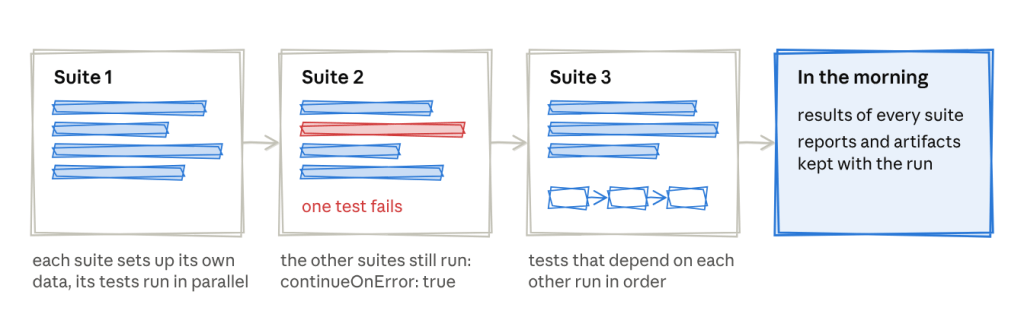
    The pipeline runs every weekday night on a fresh Ubuntu agent. Suites run one after another, because each suite sets up its own data, while the tests inside a suite run in parallel. The few tests in a file that really depend on each other run in order. We also set continueOnError: true in Azure Pipelines, so when one suite fails, the others still run and we see the full picture in the morning. Reports and artifacts are kept with each run, so most failures can be investigated without running anything locally.
    Where AI helped, and where it didn’t

    Converting around 200 tests is a lot of repetitive work, so we used GitHub Copilot for much of it.

    What I learned is that AI is good at following a structure, but it can’t decide what that structure should be. It only produced consistent tests after we had agreed on what a good test looks like.

    So before migrating anything with Copilot, we wrote an instructions file for the repository, which we called our constitution. It has rules split into MUST, SHOULD and WON’T, plus our file naming conventions, where things live, how tests are named and tagged, how the API services and clients are built, and how secrets and environments are configured in the pipeline.

    I can’t share our internal file, but I later wrote one in the same style for a workshop, and it’s public: AGENTS.md in my ai-assisted-testing-demo repo. It’s written for a small todo app rather than an enterprise product, but the structure is the same. A few lines from it:

    ## MUST
    - Locator priority. getByRole() → getByLabel() → getByPlaceholder() → getByText().
    - Web-first assertions only. Never page.waitForTimeout().
    - Seed data through the API, not the UI.
    ## WON'T
    - No getByTestId, no XPath, no CSS selectors.
    - No new tooling without being asked.

    The most useful rules turned out to be the ones that say what not to do. Without them, the assistant happily adds a hard wait or a new dependency to make a test pass.

    Then we wrote one migration prompt that walks through a C# test step by step and says where each old pattern should go:

    StepC# (before)TypeScript (after)
    1. Test dataHardcoded GUIDsData loaded from the environment: JSON.parse(process.env.PROJECT_DATA)
    2. Authenticationawait Login(AdminUser) inside each testtest.use({ storageState }) at describe level
    3. Test methods[Test] async Task ...test('TC{ID}: description', async ({ pages, adminAPIService }) => { ... })
    4. SetupData fetched or created inside the testtest.beforeEach() with module-level variables
    5. TeardownAddTearDownActions(...)test.afterEach()
    6. Real-time eventsRunAndWaitForResponseAsynca runAndWaitForSignalR(ws, callback, event) helper

    With both in place, the tests Copilot produced looked like the ones we wrote by hand, and code reviews could focus on whether the logic was right rather than on style. When the output was messy, it usually meant our own rules were unclear in that area, which was useful to find out.

    What the framework looks like now

    config/ environment and app configuration
    helpers/
    apifactory/ API service and client layer
    datafactory/ test data management
    fixtures/ Playwright fixture definitions
    pages/ Page Object Models
    tests/
    {suite_name}/ one folder per test suite
    *.spec.ts test specs
    precondition.data.ts the suite's initial data definition
    precondition.ts suite setup: auth and seed data, adjusted per suite
    playwright.config.ts

    Test names follow one pattern, so a failure in the report already tells you what broke:

    {UI|API}{TestID}: Specific scenario - expected outcome
    UI80105: Manager adds a project shared with all users - should be visible to everyone
    API80201: Contributor adds a project via API - should be forbidden

    Tags let us choose what to run: @ui for end-to-end UI scenarios, @api for API scenarios and @smoke for the smoke set.

    So far we’ve migrated around 200 tests. The suite runs about 30% faster than before, and we see around 40% fewer flaky failures.

    The tests themselves are also shorter and easier to read, they depend much less on existing data, and more checks now run at the API level instead of through the UI. Along the way we switched to accessibility-first locators like getByRole and getByLabel, and we ended up with a written guide that other teams can use for their own migrations.

    Takeaways for your own migration

    1. Don’t just translate, decide the target architecture first. The language change is the easy part.
    2. Question every test, not only the framework. Ask whether each check really needs a browser. Moving checks down to the API and unit level makes the suite faster and less flaky.
    3. Fix test data before anything else. Documented preconditions and isolated data make everything else possible, including parallel runs.
    4. Choose your data strategy deliberately. Always generating and always reusing both have costs. A flag that switches between them gives you speed and reliability.
    5. Log in once per role. Saved sessions make tests faster and more stable, and they can make MFA environments testable.
    6. Put CI in place on day one. Let the pipeline tell you what’s broken while the design is still easy to change.
    7. Give AI rules before you give it work. A clear constitution and an explicit migration prompt turn an assistant into a consistent pair of hands.

    What’s next

    We’re finishing the remaining suites, automating the creation of organisations, projects and users, expanding coverage, and tagging a proper smoke checklist.

    If you’ve been through a migration like this, I’d be curious to hear what surprised you. You can find me on LinkedIn.

  • What makes PactumJS awesome? A quick look at its best features.

    What makes PactumJS awesome? A quick look at its best features.

    1. Introduction
      1. Fluent and expressive syntax
      2. Data Management
        1. Data Templates
        2. Data Store for Dynamic Values
      3. Built-In Schema Validation
      4. Flexible Assertions
      5. Default Configuration 
    2. Conclusion
    3. Resources

    Introduction

    I’ve spent a fair bit of time writing API test automation. After exploring a few JavaScript-based tools and libraries, I’ve found Pactum to be particularly powerful. I wanted to take a moment to share a brief overview of my experience and why I think it stands out.

    If you’re setting up a PactumJS project from scratch, I recommend starting with the official Quick Start guide, which covers installation and basic setup clearly. Additionally, this article by Marie Cruz offers a great walkthrough of writing API tests with PactumJS and Jest, especially useful for beginners.

    Fluent and expressive syntax

    One of the aspects I appreciate the most is how naturally you can chain descriptive methods from the spec object to build complex requests with support for headers, body payloads, query parameters, and more.

    Example: 

    it('POST with existing username and valid password', async () => {
            await spec()
                .post('/auth/login')             .inspect()
                .withHeaders('Content-Type', 'application/json')
                .withJson({
                    '@DATA:TEMPLATE@': 'ExistingUser'
                })
                .expectStatus(200) # assertion
                .expectJsonSchema(authenticationSchema) # assertion
        })
    

    More on request making: https://github.com/pactumjs/pactum/wiki/API-Testing#request-making 

    Data Management

    Data Management is a critical aspect of test automation and often one of the more challenging pain points in any automation project. Test suites frequently reuse similar request payloads, making it difficult to maintain and organize these payloads when they are scattered across different test files or folders. Without a structured approach, this can lead to duplication, inconsistency, and increased maintenance overhead. So, it is important to have an intuitive way to handle data in the test framework. 

    In PactumJS, data management is typically handled using data templates and data stores. These help you define reusable request bodies, dynamic data, or test user information in a clean and maintainable way.

    Data Templates

    Data Templates help you define reusable request bodies and user credentials. Templates can also be locally customized within individual tests without affecting the original definition.

    For example, in testing different authentication scenarios:

    1. Valid credentials
    2. Invalid password
    3. Non-existing user

    Rather than hard-coding values in each test, as it is done below: 

    describe('/authenticate', () => {
        it('POST with existing username and valid password', async () => {
            await spec()
                .post('/auth/login')
                .inspect()
                .withHeaders('Content-Type', 'application/json')
                .withJson({
                    username: process.env.USERNAME,
                    password: process.env.PASSWORD,
                })
                .expectStatus(200)
                .expectJsonSchema(authenticationSchema)
        })
    
        it('POST with existing username and invalid password', async () => {
            await spec()
                .post('/auth/login')
                .inspect()
                .withHeaders('Content-Type', 'application/json')
                .withJson({
                    username: process.env.USERNAME,
                    password: faker.internet.password(),
                })
                .expectStatus(401)
                .expectJsonMatch('error', 'Invalid credentials')
        })
    
        it('POST with non-existing username and password', async () => {
            await spec()
                .post('/auth/login')
                .inspect()
                .withHeaders('Content-Type', 'application/json')
                .withJson({
                    username: faker.internet.username(),
                    password: faker.internet.password(),
                })
                .expectStatus(401)
                .expectJsonMatch('error', 'Invalid credentials')
        })
    })

    define reusable templates:

    // auth.js
    
    export function registerAuthTemplates() {
      stash.addDataTemplate({
        ExistingUser: {
            username: process.env.USERNAME,
            password: process.env.PASSWORD,
        },
        NonExistingUser: {
            username: faker.internet.username(),
            password: faker.internet.password(),
        }
    });
    }

    Then load them in global setup:

    // registerDataTemplates.js
    
    import { registerAuthTemplates } from "./auth.js";
    
    export function registerAllDataTemplates() {
        registerAuthTemplates();
      }

    Now, tests become cleaner and easier to maintain:

     it('POST with non-existing username and password', async () => {
            await spec()
                .post('/auth/login')
                .inspect()
                .withHeaders('Content-Type', 'application/json')
                .withJson({
                    '@DATA:TEMPLATE@': 'NonExistingUser'
                })
                .expectStatus(401)
                .expectJsonMatch('error', 'Invalid credentials')
        })

    Want to override part of a template? 

    Use @OVERRIDES@:

     it('POST with existing username and invalid password', async () => {
            await spec()
                .post('/auth/login')
                .inspect()
                .withHeaders('Content-Type', 'application/json')
                .withJson({
                    '@DATA:TEMPLATE@': 'ExistingUser',
                    '@OVERRIDES@': {
                        'password': faker.internet.password()
                      }
                })
                .expectStatus(401)
                .expectJsonMatch('error', 'Invalid credentials')
        })

    This approach improves consistency and reduces duplication. When credential details change, updates can be made centrally in the datafactory without touching individual tests. As a result, test logic remains clean, focused on validating behaviour rather than being cluttered with data setup.

    More information on data templates: https://pactumjs.github.io/guides/data-management.html#data-template 

    Data Store for Dynamic Values

    In integration and e2e API testing, one common challenge is managing dynamic data between requests. For example, you might need to extract an authentication token from an authentication response and use it in the header of subsequent requests. Without a clean way to store and reuse this data, tests can become messy, brittle, and hard to maintain.

    PactumJS provides a data store feature that allows you to save custom response data during test execution in a clean way.

    Example:

    Suppose you want to send a POST request to create a room, but the endpoint requires authentication. First, you make an authentication request and receive a token in the response. Using data store functionality, you can capture and store this token, then inject it into the headers of the room creation request. 

    describe('POST Create a New Room', () => {
    
        beforeEach(async () => {
            await spec()
                .post('/auth/login')
                .withHeaders('Content-Type', 'application/json')
                .withJson({
                    '@DATA:TEMPLATE@': 'ExistingUser'
                }).stores('token', 'token')
        });
    
    
        it('POST: Create a New Room', async () => {
            await spec()
                .post('/room')
                .inspect()
                .withHeaders('Content-Type', 'application/json')
                .withHeaders('Cookie', 'token=$S{token}')
                .withJson({ '@DATA:TEMPLATE@': 'RandomRoom' })
                .expectStatus(200)
                .expectBody({
                    "success": true
                })
    
    })

    Data store functionality also supports json-query libraries. It enables you to extract and store specific values from complex JSON responses. This is particularly helpful when dealing with nested structures, where you only need to capture a portion of the response—such as an ID, token, or status—from a larger payload.

    Example:

    await spec()
                .get('/room')
                .inspect()
                .withHeaders('Content-Type', 'application/json')
                .expectStatus(200)
                .stores('roomId', `rooms[roomName=${roomName}].roomid`);
    
            await spec()
                .get(`/room/$S{roomId}`)
                .inspect()
                .withHeaders('Content-Type', 'application/json')
                .expectStatus(200)
                .expectJson('roomName', roomName);
        })

    More on data store: https://pactumjs.github.io/guides/data-management.html#data-store 

    Built-In Schema Validation

    Unlike other setups that require integrating libraries like zod, ajv, or custom helper functions, PactumJS allows you to validate JSON responses using the expectJsonSchema method. All you need to do is define the expected schema and apply it directly in your test, no extra configuration needed.

    For example, in an authentication test case, the response schema is defined in a separate data factory:

    export const authenticationSchema = {
        "type": "object",
        "properties": {
            "token": {
                "type": "string"
            }
        },
        "additionalProperties": false,
        "required": ["token"]
    }

    You can then validate the structure of the response like this:

    it('POST with existing username and valid password', async () => {
            await spec()
                .post('/auth/login')
                .inspect()
                .withHeaders('Content-Type', 'application/json')
                .withJson({
                    '@DATA:TEMPLATE@': 'ExistingUser'
                })
                .expectStatus(200)
                .expectJsonSchema(authenticationSchema)
        })

    Flexible Assertions

    Most REST API responses return data in JSON format that must be validated. Fortunately, PactumJS provides a powerful and expressive assertion system that goes far beyond basic status code checks. Its assertion system allows for 

    1. Deep JSON matching:
    await spec()
        .get(`/room/$S{roomId}`)
        .inspect()
        .expectStatus(200)
        .expectJson('roomName', roomName);
    })
    it('POST with non-existing username and password', async () => {
         await spec()
            .post('/auth/login')
            .inspect()
            .withJson({
                '@DATA:TEMPLATE@': 'NonExistingUser'
            })
            .expectStatus(401)
            .expectJsonMatch('error', 'Invalid credentials')
        })
    1. Partial comparisons:
    it('posts should have a item with title -"some title"', async () => {
      const response = await pactum.spec()
        .get('https://jsonplaceholder.typicode.com/posts')
        .expectStatus(200)
        .expectJsonLike([
          {
            "userId": /\d+/,
            "title": "some title"
          }
        ]);
    });
    1. Path-Based Validation:
    it('get people', async () => {
      const response = await pactum.spec()
        .get('https://some-api/people')
        .expectStatus(200)
        .expectJson({
          people: [
            { name: 'Matt', country: 'NZ' },
            { name: 'Pete', country: 'AU' },
            { name: 'Mike', country: 'NZ' }
          ]
        })
        .expectJsonAt('people[country=NZ].name', 'Matt')
        .expectJsonAt('people[*].name', ['Matt', 'Pete', 'Mike']);
    });
    1. Dynamic Runtime Expressions:
    it('get users', async () => {
      await pactum.spec()
        .get('/api/users')
        .expectJsonLike('$V.length === 10'); // api should return an array with length 10
        .expectJsonLike([
          {
            id: 'typeof $V === "string"',
            name: 'jon',
            age: '$V > 30' // age should be greater than 30
          }
        ]);
    });

    And all of them are in a clean and readable format. 

    For example, you can validate only parts of a response, use regex or custom matchers, and even plug in JavaScript expressions or reusable assertion handlers. In my opinion, this level of granularity is a game-changer compared to assertion styles in other frameworks.

    Check more in the official documentation: https://github.com/pactumjs/pactum/wiki/API-Testing#response-validation 

    Default Configuration 

    To reduce repetition and keep tests clean, PactumJS allows you to define default values that apply globally across your test suite — such as headers, base URL, and request timeouts. This helps maintain consistency and simplifies test configuration.

    Here’s how it can be implemented:

    before(() => {
      request.setBaseUrl(process.env.BASE_URL);
      request.setDefaultHeaders('Content-Type', 'application/json');
    });

    More information you can find here: https://github.com/pactumjs/pactum/wiki/API-Testing#request-settings 

    Conclusion

    In my experience, PactumJS has proven to be a well-designed and developer-friendly tool for API test automation. Its fluent syntax, robust data handling, and built-in features like schema validation and dynamic stores eliminate the need for developing third-party solutions for the test framework.

    If you’re working with API testing in JavaScript / Typescript, PactumJS is definitely worth a look.

    Resources

    1. You can find the complete set of test cases, data templates, and helper functions shown in this post in the GitHub Repo. 
    2. Official PactumJS Documentation: https://pactumjs.github.io/ 
    3. PactumJS WiKi Page: https://github.com/pactumjs/pactum/wiki/API-Testing 
    4. Code Examples in PactumJS GitHub: https://github.com/pactumjs/pactum-examples 
  • Automating Contract Testing in a CI/CD Pipeline with GitHub Actions

    Automating Contract Testing in a CI/CD Pipeline with GitHub Actions

    Using a Pact Broker to Manage Contracts Across Microservices

    In the previous article, I raised an important question: What if the provider and consumer microservices do not share the same repository but still need access to the contract from a third-party source? The solution to this challenge is the Pact Broker.

    In this article, we will explore how the Pact Broker works and how to implement pipeline using GitHub Actions.

    When Do You Need a Pact Broker?

    A Pact Broker is essential in scenarios where:

    • The provider and consumer microservices are in separate repositories but must share the same contract.
    • You need to manage contracts across different branches and environments.
    • Coordinating releases between multiple teams is required.

    Options for Setting Up a Pact Broker

    There are multiple ways to set up a Pact Broker:

    1. Own Contract Storage Solution – Implement your own contract-sharing mechanism.
    2. Hosted Pact Broker (PactFlow) – A cloud-based solution provided by SmartBear.
    3. Self-Hosted Open-Source Pact Broker – Deploy and manage the Pact Broker on your infrastructure.

    As a starting point, PactFlow is a great solution due to its ease of use.

    Publishing Contracts to the Pact Broker

    For demonstration purposes, we will use the free version of PactFlow. Follow these steps to publish contracts:

    1. Sign Up for PactFlow

    Visit PactFlow and create a free account.

    2. Retrieve Required Credentials

    • Broker URL: Copy the URL from the address bar (e.g., https://custom.pactflow.io/).
    • Broker API Token: Navigate to Settings → API Tokens and copy the read/write token for CI/CD pipeline authentication.

    3. Setting Up a CI/CD Pipeline with GitHub Actions

    Setting up CI/CD pipeline using GitHub Actions.

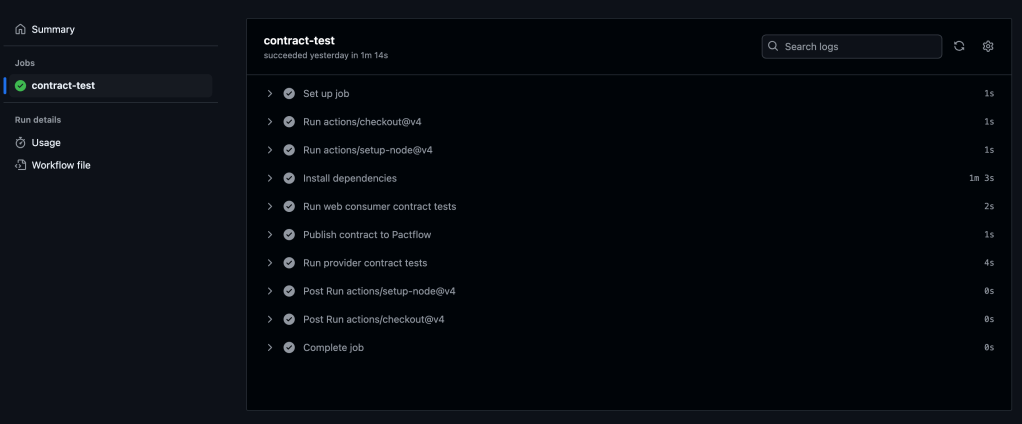
    We will configure GitHub Actions to trigger on a push or merge to the main branch. The workflow consists of the steps displayed on the diagram.

    To set up GitHub Actions, create a .yml file in the .github/workflows directory. In this example, we’ll use contract-test-sample.yml:

    name: Run contract tests
    
    on: push
    
    env:
      PACT_BROKER_BASE_URL: ${{ secrets.PACT_BROKER_BASE_URL }}
      PACT_BROKER_TOKEN: ${{ secrets.PACT_BROKER_TOKEN }}
    
    jobs:
      contract-test:
        runs-on: ubuntu-latest
        steps:
          - uses: actions/checkout@v4
          - uses: actions/setup-node@v4
            with:
              node-version: 18
          - name: Install dependencies
            run: npm install
          - name: Run web consumer contract tests
            run: npm run test:consumer
          - name: Publish contract to PactFlow
            run: npm run publish:pact
          - name: Run provider contract tests
            run: npm run test:provider

    Before running the workflow, store the required secrets in your GitHub repository:

    1. Navigate to Repository → Settings → Secrets and Variables.
    2. Create two secrets:
      • PACT_BROKER_BASE_URL
      • PACT_BROKER_TOKEN

    Save, commit, and push your changes to the remote repository.

    Navigate to the Actions tab in GitHub to verify if the pipeline runs successfully.

    You should see all the steps running successfully like on the screenshot below:

    7. Verifying the Contract in PactFlow

    Once the pipeline runs successfully:

    • Navigate to PactFlow.
    • Verify if the contract has been published.
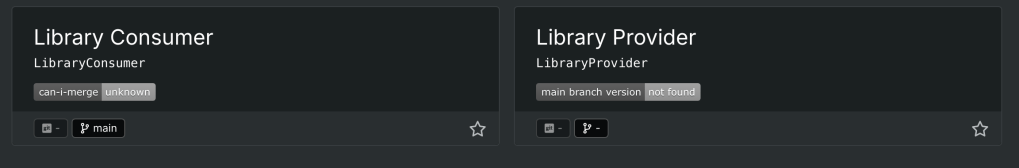
    • You should see two microservices and the contract established between them.
    Two microservices – Library Consumer and Library Provider
    Pact between two microservices, which is published and stored in PactFlow

    Configuring Contract Versioning

    If there are changes in the contract (e.g., if a new version of a consumer or provider is released), versioning should evolve too. Automating this process is crucial.

    A recommended approach is using GitHub Commit ID (SHA), ensuring that contract versions are traceable to relevant code changes.

    1. Define the Versioning Variable

    In the contract-test-sample.yml file, introduce a new environment variable GITHUB_SHA:

    GITHUB_SHA: ${{ github.sha }}

    2. Update the Pact Publish Script

    Modify the pact:publish script to use the automatically generated version:

    "publish:pact": "pact-broker publish ./pacts --consumer-app-version=$GITHUB_SHA --tag=main --broker-base-url=$PACT_BROKER_BASE_URL --broker-token=$PACT_BROKER_TOKEN"

    3. Update provider options with providerVersion value:

    const opts = {
                provider: "LibraryProvider",
                providerBaseUrl: "http://localhost:3000",
                pactBrokerToken: process.env.PACT_BROKER_TOKEN,
                providerVersion: process.env.GITHUB_SHA,
                publishVerificationResult: true,
                stateHandlers: {
                    "A book with ID 1 exists": () => {
                        return Promise.resolve("Book with ID 1 exists")
                    },
                },
            }

    Configuring Branches for Contract Management

    If multiple people are working on the product in different branches, it is crucial to assign contracts to specific branches to ensure accurate verification.

    1. Define the Branching Variable

    Add GITHUB_BRANCH to the .yml file:

    GITHUB_BRANCH: ${{ github.ref_name }}

    2. Update the Pact Publish Script for Branching

    Modify pact:publish to associate contracts with specific branches:

    "publish:pact": "pact-broker publish ./pacts --consumer-app-version=$GITHUB_SHA --branch=$GITHUB_BRANCH --broker-base-url=$PACT_BROKER_BASE_URL --broker-token=$PACT_BROKER_TOKEN"

    3. Update provider options with providerVersionBranch value:

    const opts = {
                provider: "LibraryProvider",
                providerBaseUrl: "http://localhost:3000",
                pactBrokerToken: process.env.PACT_BROKER_TOKEN,
                providerVersion: process.env.GITHUB_SHA,
                providerVersionBranch: process.env.GITHUB_BRANCH,
                publishVerificationResult: true,
                stateHandlers: {
                    "A book with ID 1 exists": () => {
                        return Promise.resolve("Book with ID 1 exists")
                    },
                },
            }

    Using the can-i-deploy tool

    The can-i-deploy tool is a Pact feature that queries the matrix table to verify if a contract version is safe to deploy. This ensures that new changes are successfully verified against the currently deployed versions in the environment.

    Running can-i-deploy for consumer:

    pact-broker can-i-deploy --pacticipant LibraryConsumer --version=$GITHUB_SHA

    Running can-i-deploy for provider:

    pact-broker can-i-deploy --pacticipant LibraryProvider --version=$GITHUB_SHA

    If successful, it confirms that the contract is verified and ready for deployment.

    To reuse these commands, we will create scripts for verification in package.json file:

    "can:i:deploy:consumer": "pact-broker can-i-deploy --pacticipant LibraryConsumer --version=$GITHUB_SHA"
    
    "can:i:deploy:provider": "pact-broker can-i-deploy --pacticipant LibraryProvider --version=$GITHUB_SHA"

    And then update GitHub Actions pipeline:

    name: Run contract tests
    
    on: push
    
    env:
      PACT_BROKER_BASE_URL: ${{ secrets.PACT_BROKER_BASE_URL }}
      PACT_BROKER_TOKEN: ${{ secrets.PACT_BROKER_TOKEN }}
      GITHUB_SHA: ${{ github.sha }}
      GITHUB_BRANCH: ${{ github.ref_name }}
    
    jobs:
      contract-test:
        runs-on: ubuntu-latest
        steps:
          - uses: actions/checkout@v4
          - uses: actions/setup-node@v4
            with:
              node-version: 18
          - name: Install dependencies
            run: npm i
          - name: Run web consumer contract tests
            run: npm run test:consumer
          - name: Publish contract to Pactflow
            run: npm run publish:pact
          - name: Run provider contract tests
            run: npm run test:provider
          - name: Can I deploy consumer?
            run: npm run can:i:deploy:consumer
          - name: Can I deploy provider?
            run: npm run can:i:deploy:provider

    Add changes, commit and push. Navigate to the Actions tab in GitHub to verify if the pipeline runs successfully.

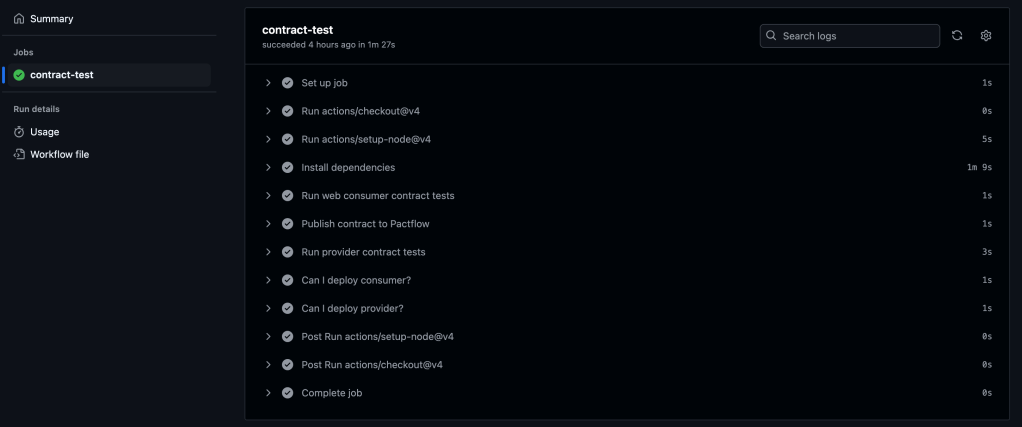
    You should see all the steps running successfully like on the screenshot below:

    GitHub Actions pipeline contains extra steps, which verify if a contract version is safe to deploy

    Conclusion

    The Pact Broker is important for managing contracts across microservices, ensuring smooth collaboration between independent services. By automating contract versioning, branch-based contract management, and deployment workflows using GitHub Actions, teams can can reduce deployment risks, improve service reliability, and speed-up release cycles.

    For a complete implementation, refer to the final version of the code in the repository.

  • Contract Testing: Who’s Who in the Process

    Contract Testing: Who’s Who in the Process

    Introduction

    Today, I want to introduce you to the concept of contract testing using an analogy—buying the house of your dreams 🏡. Whether you already own your dream home or are still searching for it, you probably know the excitement and anticipation that comes with the process.

    Imagine you’ve finally found the perfect house. You’re happy to move forward, but before the keys are in your hand, it’s crucial to set clear expectations with the seller. This involves agreeing on the details: the price, the condition of the house, and any other terms. To formalize this, a contract is drawn up, and a neutral party, like a notary or bank, helps ensure everything is clear and fair.

    This scenario mirrors contract testing in software development, where a consumer (the buyer) and a provider (the seller) agree on a contract to ensure their interactions meet expectations. The contract broker (like the notary) acts as a mediator to validate and enforce these agreements.

    Let’s break this analogy down further.

    Consumer.

    In this scenario you’re a consumer. You have specific expectations: size, number of rooms, location, price, neighbourhood, etc. 

    In contract testing, the consumer is a service or application that needs to consume data or services from a provider. The consumer is usually a web or mobile application making a request to a backend service, also it could be another service calling a backend service.  

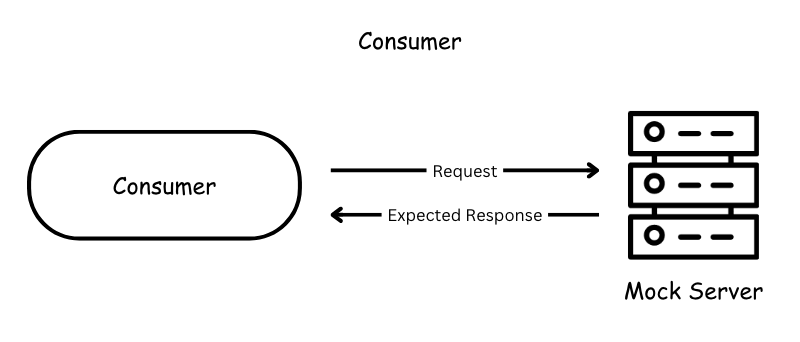
    A consumer test verifies that the consumer correctly creates requests, handles provider responses as expected, and uncovers any misunderstandings about the provider’s behavior.

    Provider

    Then, the seller is the person offering the house. They promise certain features in the house: a garden, a modern kitchen, friendly neighbourhood and so on. 

    Provider on the other side of the consumer in contract testing that promises to deliver specific data or functionality. Usually it is a backend service. 

    Contract

    The contract is the written agreement between you and the seller. It ensures both parties understand and agree on what is being provided and what is expected (e.g., the price, delivery date, features of the house).

    The contract is no different in software. The contract is a formal agreement between the consumer and provider about how they will interact (e.g., API specifications, request/response formats).

    Hmmm.. not really! Contract isn’t the same as JSON Schema. This article explains well the difference between schema-based and contract-based testing. 

    In short: A schema is a structural blueprint or definition of how data in JSON is organized. It describes the structure, format, and relationships of data. 

    But the schema does not specify how the data should be used, when it should be provided, or how the interaction between the consumer and provider should behave. It’s purely about the data format and structure.

    A contract includes the schema but also goes beyond it to define the behavioral and interaction agreements between the consumer and provider.

    Contract includes following data:

    • The name of the consumer and provider
    • Data requirements for the request
    • Interactions between consumer and provider
    • Matching rules for the dynamic values
    • Environment and deployment information

    Contract Broker

    The contract broker, like a bank or notary, helps validate and mediate the agreement. They ensure that both parties adhere to their commitments.

    In contract testing, the contract broker could be a tool or framework (e.g., Pact) that stores and validates contracts. It ensures the provider and consumer stick to their agreed-upon specifications.

    The broker helps verify the compatibility between the two parties independently, ensuring that both can work together smoothly.

    Can-I-Deploy Tool

    To enable consumers and providers to check if they can deploy their changes to production, Pact provides a command-line interface (CLI) tool called can-i-deploy, which enables consumer and provider to determine the verification status of the contract.

    Contract testing approaches

    There are mainly two ways to approach contract testing:

    • The consumer-driven contract testing (CDCT) approach
    • The provider-driven contract testing (PDCT) approach

    In these series I am going to discuss traditional CDCT approach.

    Consumer-Driven Testing

    In the consumer-driven approach the consumer is driving the contract. As a consumer before finalizing the house purchase, you might inspect the house to confirm it meets your expectations and publish your expectations as a contract to the broker. On another side,  the seller must ensure their house is as described in the contract and ready for sale. This is like provider-side testing, ensuring they deliver what the contract specifies.

    Contract testing ensures that consumers (buyers) and providers (sellers) are on the same page regarding their expectations and deliverables, with a broker (notary or bank) facilitating the process. This approach reduces the risk of miscommunication and ensures smooth collaboration—whether you’re buying a house or building software systems.

    Conclusion

    Contract testing acts as the bridge between consumers and providers, ensuring smooth collaboration. Much like finalizing the purchase of your dream house, both parties agree on a contract that outlines expectations and deliverables, with a broker ensuring everything aligns. Whether you’re buying a house or developing software, clear agreements lead to smoother outcomes!

    Next, we’ll explore the application under test and hit the ground running with implementation!

  • “Shift-Left” Testing Strategy with Contract Testing. Introduction.

    “Shift-Left” Testing Strategy with Contract Testing. Introduction.

    The Inspiration Behind This Series

    At the end of 2024, I ordered a book Contract Testing in Action and had been waiting for the right moment to start exploring. Recently, I finally read through most of its chapters and found its insights to be handy for development teams working with microservice architectures. Inspired by the knowledge and ideas from the book, I decided to write a series of articles to share what I’ve learned and explore how these concepts can be effectively applied in real-world scenarios. This introductory article serves as the starting point, explaining what contract testing is and how it fits into a broader testing strategy.


    Testing Strategy for Microservices.

    Over the past few decades, microservice architecture became a crucial way of building modern, scalable, and reliable applications. Traditional monolithic systems, where the database and all business logic seats under a single, tightly coupled structure, have gradually taken a backseat. In their place, independently deployable and modular services—known as microservices — have became the foundation of contemporary software development. This shift enables product teams to deliver features faster and more efficiently. However, with this huge leap comes the challenge with ensuring that each microservice operates correctly both in isolation and as part of larger systems. So, planning and executing testing strategies becomes an important component of the development lifecycle. 

    The most widespread scheme of testing of any system is the one which is proposed by  Mike Cohn in his book ‘Succeeding with Agile’.

    Source: https://semaphoreci.com/blog/testing-pyramid

    Microservices often rely on APIs to exchange data, with some services acting as providers (offering data) and others as consumers (requesting and processing data). Without a clear and tested agreement—or contract—between these services, even minor changes in one service can lead to failures across the system. This is where contract testing becomes invaluable and should be included into the pyramid as well. 

    Here is the adjusted version of the pyramid:

    Why is contract testing so important?

    Let’s take a real-life example with a banking application. Imagine a banking application with the following teams and components:

    1. Frontend Application (Consumer):
      Built by a frontend team, this React-based web app allows customers to view their account balance and transaction history by making API calls to the backend.
    2. Backend API (Provider):
      Managed by a backend team, the API provides endpoints for account details, including:
      • /account/{id}/balance – Returns the account balance.

    The frontend app is integrated with the backend API, expecting the following responses:

    Account Balance Endpoint (GET /account/{id}/balance):

    {
      "accountId": "12345",
      "balance": 5000
    }

    On Friday Evening the backend engineer decides to improve the /account/{id}/balance response to rename accountId to id. The new response structure looks like this:

    {
      "id": "12345",
      "balance": 5000
    }

    The engineer deploys the change, thinking it’s a harmless addition. No contract tests are in place to verify compatibility with the frontend.

    Result:

    The frontend app’s code does not recognise the renamed accountId field and instead tries to access id under the old key. This results in an error when parsing the JSON response, as the frontend is still expecting the accountId field. As a result, the frontend fails to display the account balance and shows a blank page or an error message to customers.

    Impact Over the Weekend:

    • Customers are unable to check their account balance, leading to frustration and confusion.
    • The frontend team was unaware of the backend change until Monday morning, as there were no contract tests in place to alert them about the breaking change.
    • The downtime disrupts the customer experience, potentially destroying trust in the banking application and impacting the reputation of the service.

    What could be done better?

    With contract testing, the frontend and backend teams define a clear agreement (the “contract”) about API interactions, specifying expected fields and data types. Before deployment, both consumer (frontend) and provider (backend) teams run tests to ensure compatibility, catching issues early. By integrating contract tests into the CI/CD pipeline, breaking changes are flagged during development or staging, preventing them from reaching production. This approach ensures smooth communication between services, reduces downtime, and enforces better collaboration between teams.

    What is Contract Testing in a nutshell?

    Contract testing is a technique for testing an integration point by checking each application in isolation to ensure the messages it sends or receives conform to a shared understanding that is documented in a “contract”.

    Source: Pact Documentation.

    The contract is a JSON file containing the names of the two interacting systems: in this case, the web application and backend server. The contract also lists all interactions between the two systems. 

    In the context of the test automation pyramid, contract testing bridges the gap between unit tests and end-to-end tests by focusing on the interactions between microservices. It ensures that the consumer and provider services adhere to a shared agreement (the “contract”) regarding APIs, such as expected request and response structures. By having contract testing in place, it proactively identifies and addresses these compatibility problems earlier in the development cycle.

    There is an insightful diagram in the book “Contract Testing in Action” that illustrates how some test cases can be shifted to contract tests. This shift moves them lower in the test automation pyramid, enabling issues to be identified earlier in the development lifecycle. 

    Source: Contract Testing in Action book

    As microservices continue to dominate the landscape of software development, adopting contract testing is no longer optional—it is essential. By incorporating this practice, teams can build scalable, reliable, and user-focused applications, providing a smooth experience for end users and ensuring strong collaboration across development teams.

    In the upcoming articles, we will meet contract testing players and focus on the practical implementation of contract testing, exploring tools, techniques, and best practices to integrate testing strategy into development workflow.

    As I continue learning, I also began compiling a repository of helpful resources on contract testing to serve as a reference for myself and others exploring this topic.